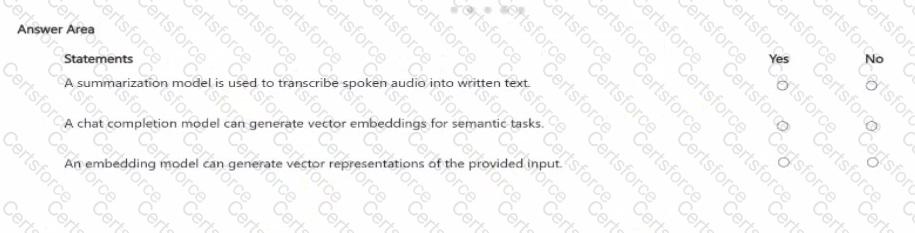
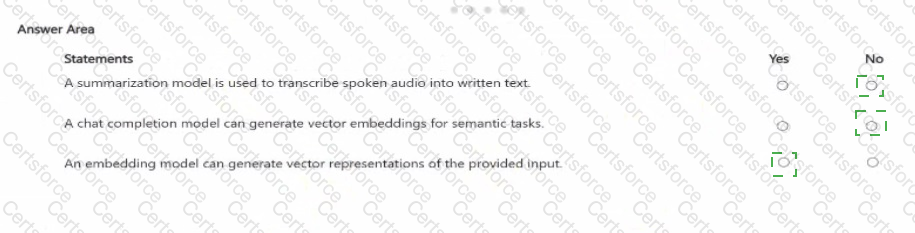
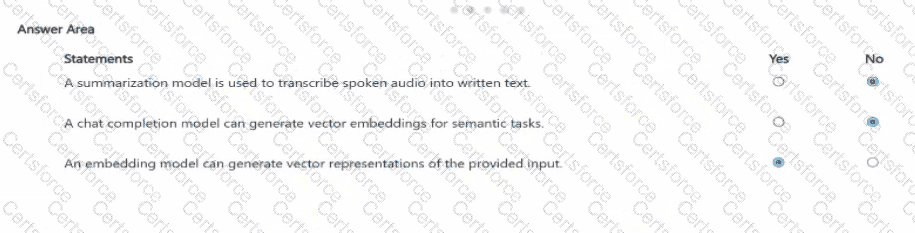
Statement 1: A summarization model is used to transcribe spoken audio into written text. = No
Summarization creates a shorter version of existing text. Transcribing spoken audio into written text is a speech recognition / speech-to-text capability, not summarization.
Statement 2: A chat completion model can generate vector embeddings for semantic tasks. = No
Chat completion models are used to generate conversational text responses. Vector embeddings for semantic search, similarity, and retrieval tasks are generated by embedding models , not chat completion models.
Statement 3: An embedding model can generate vector representations of the provided input. = Yes
This is correct. Embedding models convert input such as text into vector representations that capture semantic meaning and can be used for tasks such as similarity search, clustering, and retrieval.
Contribute your Thoughts:
Chosen Answer:
This is a voting comment (?). You can switch to a simple comment. It is better to Upvote an existing comment if you don't have anything to add.


Submit